MODEL EXPLORER / VISION MILESTONES
Bring spatial detail back into the decoder
How does a segmentation decoder recover features lost during downsampling?
RECORDED NUMERICAL EXAMPLE
Recover detail through cropped skip features.
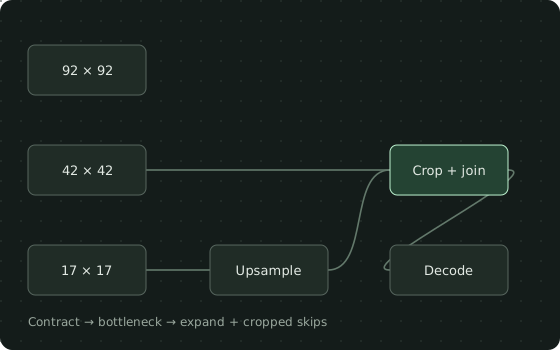
Recorded activations from a synthetic rectangle image. U-Net joins high-resolution encoder features to the expanding decoder along the channel axis. Thumbnails show spatial structure; exact dimensions and channel counts are separate.
Each square below is an average-pooled thumbnail of one recorded feature channel. The skip is center-cropped to match the upsampled decoder; concatenation keeps both channel sets. These randomly initialized features are not a learned segmentation or an explanation of pixel importance.
Min -0.01426 · Max -0.00739
Recorded cell values
| Row / col | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|---|
| 0 | -0.01343 | -0.01354 | -0.01342 | -0.01341 | -0.01426 | -0.01421 | -0.01406 | -0.01412 |
| 1 | -0.01342 | -0.01343 | -0.01303 | -0.01306 | -0.01399 | -0.01416 | -0.01409 | -0.01412 |
| 2 | -0.01344 | -0.01347 | -0.013 | -0.01299 | -0.014 | -0.0142 | -0.01407 | -0.01413 |
| 3 | -0.01344 | -0.01347 | -0.01303 | -0.01303 | -0.01403 | -0.01421 | -0.01405 | -0.01413 |
| 4 | -0.007716 | -0.00776 | -0.007486 | -0.00739 | -0.00947 | -0.009587 | -0.009528 | -0.009548 |
| 5 | -0.007714 | -0.007723 | -0.007477 | -0.007394 | -0.009329 | -0.00947 | -0.00948 | -0.009541 |
| 6 | -0.007723 | -0.007903 | -0.007851 | -0.007756 | -0.009723 | -0.009809 | -0.009682 | -0.009583 |
| 7 | -0.007701 | -0.007882 | -0.007996 | -0.007966 | -0.009891 | -0.009813 | -0.00965 | -0.009546 |
Min 0 · Max 0
Recorded cell values
| Row / col | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|---|
| 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 1 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 2 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 3 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 4 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 5 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 6 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 7 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
Min 0 · Max 0
Recorded cell values
| Row / col | 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 |
|---|---|---|---|---|---|---|---|---|
| 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 1 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 2 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 3 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 4 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 5 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 6 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
| 7 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
Each heatmap uses its own scale. Mint is positive, rust is negative, and the lightest color is zero. Table values are rounded to four significant digits.
Bars share one scale within this example. Values are rounded to four significant digits.
- Skip spatial width before crop
- 42
- Shared width after crop
- 34
- Pixels cropped from each side
- 4
Verified by the local recipe
- Valid convolutions map 96×96 inputs to two-channel 56×56 logits
- Upsampling to 34×34 joins eight decoder and eight centrally cropped skip channels
- The crop preserves exact skip values, rather than interpolating them
- A skip-only loss sends gradients through the cropped region and not through the decoder branch
Download the source and run.py to reproduce these checks. Choosing an example here replays recorded values.
THE SAME MODEL, ON YOUR MACHINE
Pick up where
the graph leaves off.
Trace a U-shaped network through its bottleneck, then inspect the cropped feature maps that rejoin its expanding path.
Use in VS Code ↗1. Save these files in one folder
2. Reproduce the example
Use Python 3.13 in a dedicated environment, matching the tested recipe. These commands are for macOS / Linux shells.
python3.13 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python run.py
Expected output: [1,2,56,56]
Input 1: [1,1,96,96] · float32 randn · CPU / eval · seed 0
3. Open the source in TensorViz
Install the preview, open this folder in local VS Code, and choose Open as Graph above TinyUNet in model.py. Select your Python environment. Save before choosing Validate.
Installation and supported setup ↗
The recipe was run with Python 3.13.13 and Torch 2.7.1. This is an untrained example; a successful shape check does not measure accuracy.
ABOUT THIS EXAMPLE
Trace a U-shaped network through its bottleneck, then inspect the cropped feature maps that rejoin its expanding path.
Architecture · 2015
U-Net
Two down/up levels with widths 4/8/16, valid 3×3 convolutions, transposed-convolution upsampling and center-cropped skips. A 96×96 input produces 56×56 two-class logits.
Source, capture & limitations +
Untrained reduced network with two levels instead of the original four. No biomedical dataset, elastic-augmentation recipe, overlap-tile inference or segmentation accuracy. Heatmaps summarize one feature channel with 8×8 average-pooled thumbnails.
Original TensorViz teaching example. PyTorch provides the underlying operators.
No separate redistribution license has been declared for these project examples.
- Content revision
3a861b8cdaf42ce4- Source SHA-256
27af400b501694077500e40027cc19b66d217ee26708e30e805bf0e12b373dbc- Captured
- 2026-09-17 · Python 3.13.13 / Torch 2.7.1
Reduced U-Net CPU forward, exact center-crop/concatenation checks and skip-gradient support. Feature thumbnails are pooled recorded activations, not trained segmentation results.
Read the model manifest ↗