MODEL EXPLORER / ATTENTION
Inside self-attention
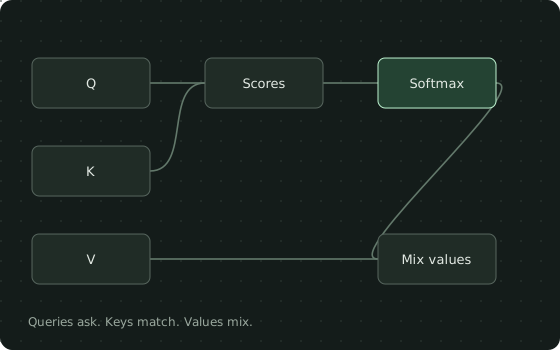
How do queries, keys and values meet?
THE SAME MODEL, ON YOUR MACHINE
Pick up where
the graph leaves off.
Trace one attention head from three projections to a weighted mixture, then follow the residual back to the output.
Use in VS Code ↗1. Save these files in one folder
2. Reproduce the example
Use Python 3.13 in a dedicated environment, matching the tested recipe. These commands are for macOS / Linux shells.
python3.13 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python run.py
Expected output: [1,4,32]
Input: [1,4,32] · float32 ones · CPU / eval · seed 0
3. Open the source in TensorViz
Install the preview, open this folder in local VS Code, and choose Open as Graph above TokenMixer in model.py. Select your Python environment. Save before choosing Validate.
Installation and supported setup ↗
The recipe was run with Python 3.13.13 and Torch 2.7.1. This is an untrained example; a successful shape check does not measure accuracy.
ABOUT THIS EXAMPLE
Trace one attention head from three projections to a weighted mixture, then follow the residual back to the output.
Source, capture & limitations +
One untrained, unmasked attention head over four 32-wide tokens; not a complete language model. TensorViz groups the score calculation and weighted value mixture into two Python nodes. Source shows the exact operations.
Original TensorViz teaching example. PyTorch provides the underlying operators.
No separate redistribution license has been declared for these project examples.
- Content revision
d2b8dd93364c22a1- Source SHA-256
c8c21db7fcd9192b0f641cafd9e216a291d49926e230f137dc81a95adada0adb- Captured
- 2026-09-17 · Python 3.13.13 / Torch 2.7.1
One CPU forward with float32 ones; untrained example, no accuracy claim. Installed VS Code workflow not separately verified for this example.
Read the model manifest ↗