MODEL EXPLORER / MODERN LLMS
Where the normalization goes
What happens to the shortcut when normalization moves?
RECORDED NUMERICAL EXAMPLE
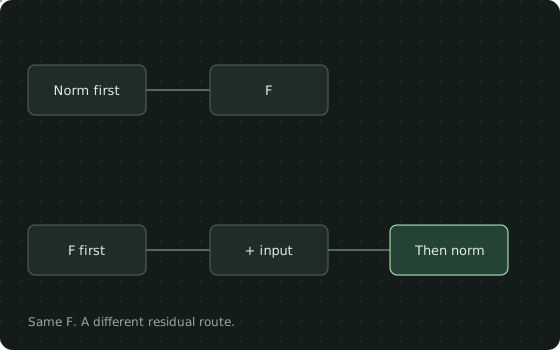
Move the normalization. Keep F fixed.
Recorded CPU calculations with the same eight-feature input, matching branch weights, and matching LayerNorm parameters.
Both branches have the same F weights and LayerNorm parameters. Only the placement changes: x + F(Norm(x)) versus Norm(x + F(x)).
Bars share one scale within this example. Values are rounded to four significant digits.
- Pre-norm distance from input
- 1.684
- Post-norm distance from input
- 13.55
Verified by the local recipe
- Both placements use identical branch weights
- Zeroing F leaves pre-norm's identity path intact but post-norm still normalizes
- The zero-branch pre-norm path has the identity derivative
Download the source and run.py to reproduce these checks. Choosing an example here replays recorded values.
THE SAME MODEL, ON YOUR MACHINE
Pick up where
the graph leaves off.
Keep the learned branch fixed while comparing pre-norm and post-norm, then zero the branch to expose the identity path.
Use in VS Code ↗1. Save these files in one folder
2. Reproduce the example
Use Python 3.13 in a dedicated environment, matching the tested recipe. These commands are for macOS / Linux shells.
python3.13 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python run.py
Expected output: [2,1,4,8]
Input 1: [1,4,8] · float32 randn · CPU / eval · seed 0
3. Open the source in TensorViz
Install the preview, open this folder in local VS Code, and choose Open as Graph above NormPlacement in model.py. Select your Python environment. Save before choosing Validate.
Installation and supported setup ↗
The recipe was run with Python 3.13.13 and Torch 2.7.1. This is an untrained example; a successful shape check does not measure accuracy.
ABOUT THIS EXAMPLE
Keep the learned branch fixed while comparing pre-norm and post-norm, then zero the branch to expose the identity path.
Component · 2020
Pre-LN / Post-LN
An eight-feature residual sublayer with a linear F isolates normalization placement. The cited 2020 paper analyzes the already proposed pre-LN design.
Source, capture & limitations +
Both branches use LayerNorm. This comparison changes placement, not RMSNorm versus LayerNorm. Forward values and a local derivative do not establish training stability for a full network.
Original TensorViz teaching example. PyTorch provides the underlying operators.
No separate redistribution license has been declared for these project examples.
- Content revision
498438923bc427aa- Source SHA-256
cb5e47f19519d2dba172bb95821ca71583e7123cd9c3f3b92618ee3a58436a62- Captured
- 2026-09-17 · Python 3.13.13 / Torch 2.7.1
One seeded CPU forward plus identical-weight, zero-branch and local-derivative checks. No optimization or training-speed benchmark.
Read the model manifest ↗