MODEL EXPLORER / ATTENTION SYSTEMS
Compress the cache, keep position separate
What must MLA store to avoid reconstructing every key and value?
RECORDED NUMERICAL EXAMPLE
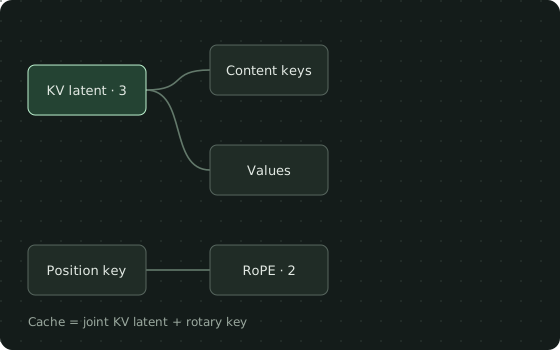
Cache a latent plus the positional key.
Recorded decoding comparisons for 1, 3 and 6 prefix tokens. Expanded storage counts 8 content-key + 8 value + 2 shared rotary-key values per token; the compact cache needs 3 + 2. These teaching dimensions are not DeepSeek-V2's production dimensions.
The cache retains the joint KV latent and a separate rotated key. The content-key up-projection is absorbed into the query calculation; the value up-projection is absorbed into the output projection. The positional path stays separate because token-dependent rotations cannot be freely reordered with learned matrices.
Bars share one scale within this example. Values are rounded to four significant digits.
- Compact cache · scalar values
- 5
- Expanded content K/V + shared rotary key · scalar values
- 18
- Maximum output difference
- 1.388e-17
Verified by the local recipe
- Compressed-cache and absorbed-weight inference matches reconstructed attention for every prefix
- Cache stores three latent and two rotary-key values per token; query latents are not cached
- Causal outputs cannot change when only future inputs change
- The decoupled rotary path preserves pair norms and contributes to this example's output
Download the source and run.py to reproduce these checks. Choosing an example here replays recorded values.
THE SAME MODEL, ON YOUR MACHINE
Pick up where
the graph leaves off.
Trace joint KV compression and decoupled RoPE, then compare reconstructed attention with an absorbed-weight decoding calculation.
Use in VS Code ↗1. Save these files in one folder
2. Reproduce the example
Use Python 3.13 in a dedicated environment, matching the tested recipe. These commands are for macOS / Linux shells.
python3.13 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python run.py
Expected output: [1,6,8]
Input 1: [1,6,8] · float32 randn · CPU / eval · seed 0
3. Open the source in TensorViz
Install the preview, open this folder in local VS Code, and choose Open as Graph above LatentAttention in model.py. Select your Python environment. Save before choosing Validate.
Installation and supported setup ↗
The recipe was run with Python 3.13.13 and Torch 2.7.1. This is an untrained example; a successful shape check does not measure accuracy.
ABOUT THIS EXAMPLE
Trace joint KV compression and decoupled RoPE, then compare reconstructed attention with an absorbed-weight decoding calculation.
Component · 2024
Multi-head Latent Attention
Four heads with content/value width two and rotary width two; KV latent width three and query latent width four. Includes the shared decoupled rotary key from DeepSeek-V2 equations 9–19.
Source, capture & limitations +
An untrained MLA subsystem with reduced dimensions, not a complete DeepSeek model. The graph shows the explicit reconstructed forward; the CPU recipe separately verifies equivalent absorbed-weight inference. It includes the positional key in every cache estimate.
Original TensorViz teaching example. PyTorch provides the underlying operators.
No separate redistribution license has been declared for these project examples.
- Content revision
a52b24527129a0bd- Source SHA-256
926d62027862b2121375cb2bfd54e4947208e89e13c7385545fa8cb502cdb656- Captured
- 2026-09-17 · Python 3.13.13 / Torch 2.7.1
Reduced MLA forward and independent absorbed-weight decoding for every prefix. Cache counts are analytical scalar counts, not speed or memory benchmarks.
Read the model manifest ↗